
Architecture, AI, and the Power of Community: My Week at GIDS
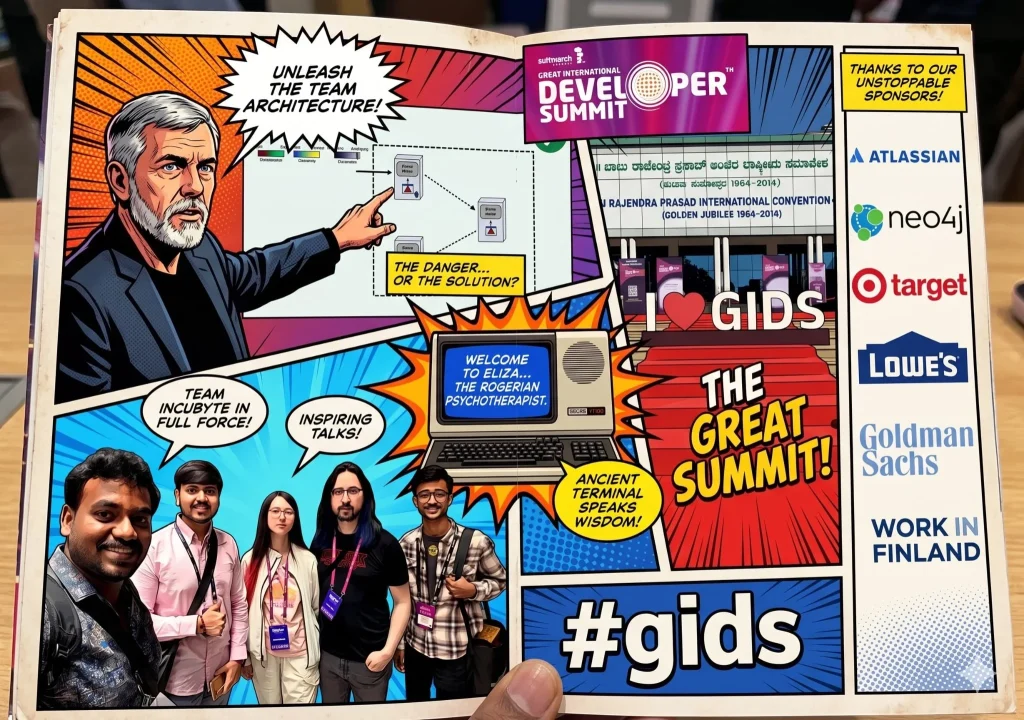
Reflections from GIDS Bangalore: architecture, AI, accessibility, community, and what a week at the conference meant for me as a software craftsperson.
Taming React Re-renders: A Guide to Optimizing Performance
A comprehensive guide to understanding and optimizing React re-renders for better application performance
Beyond Blueprints: Architecture Insights from GIDS 2025
What does it really take to design software that lasts? As a senior developer, that question is always on my mind and GIDS 2025 offered some fresh perspectives and practical answers. Architecture was a recurring theme across many sessions — not just as a technical role, but as a way of thinking. Here are some […]
Stop Testing Implementation Details in Your Frontend Code
Learn why testing implementation details makes your tests fragile and how to write better, more reliable tests that focus on user behavior.
Prompting Like a Pro: Crafting AI-Assisted Development Workflows
Trips and tricks for effective prompting
Decode LLM Quality – Eval Testing and Benchmarking LLMs: An Evaluation Guide
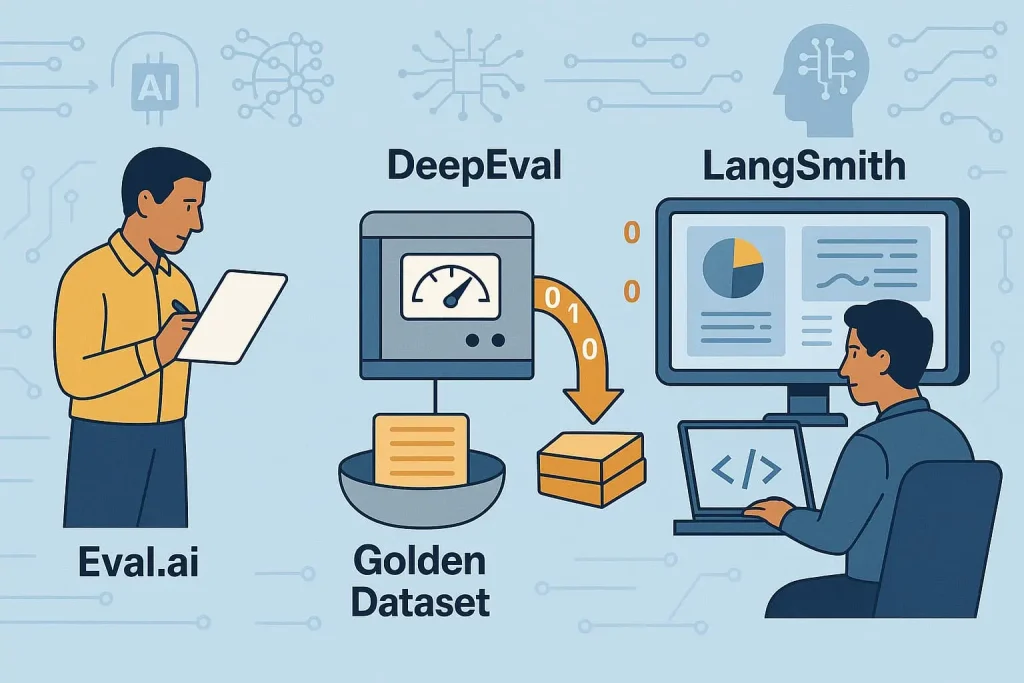
This blog chronicles a team’s journey in evaluating LLM outputs, transitioning from Eval.ai to a hybrid framework combining DeepEval’s synthetic test generation with LangSmith’s real-time observability. The result is a scalable, TypeScript-compatible evaluation system tailored for RAG applications and production-grade AI models.
We Let AI Code for Us: Prompts Were Prayers and Code Was… Interesting
A reflective account of our AI hackathon experience, highlighting key challenges, practical learnings, and actionable takeaways for effective AI-assisted development.
Its 2025 And You Should Not Write Code Without Tests
In 2025, shipping code without tests should be a total no. In a landscape where deployments happen multiple times a day and services are expected to be available 24/7, undetected regressions can lead to downtime and erode user trust. Automated tests provide a safety net that ensures changes don’t introduce unexpected behavior, offering confidence and […]
Building Quick Cue: A Chrome Extension for AI Chat Shortcuts
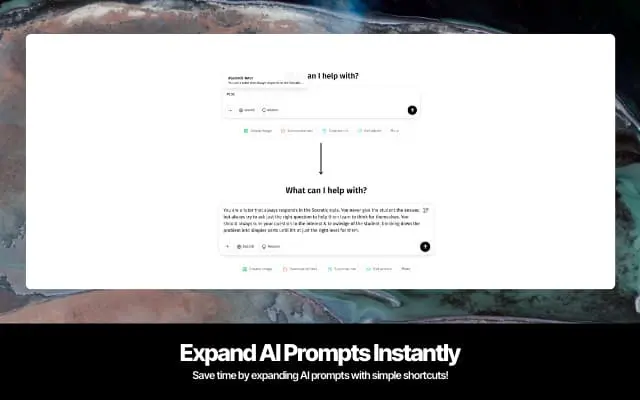
Like many AI enthusiasts, I found myself writing the same prompts repeatedly when using Claude, ChatGPT, or Gemini. This repetitive typing wasn’t just tedious—it was a clear opportunity for optimization. What if there was a way to create shorthand abbreviations that automatically expanded into full prompts? The Solution: Quick Cue This led me to develop […]
Vitest with React Testing Library: A Modern Approach to Testing React Apps
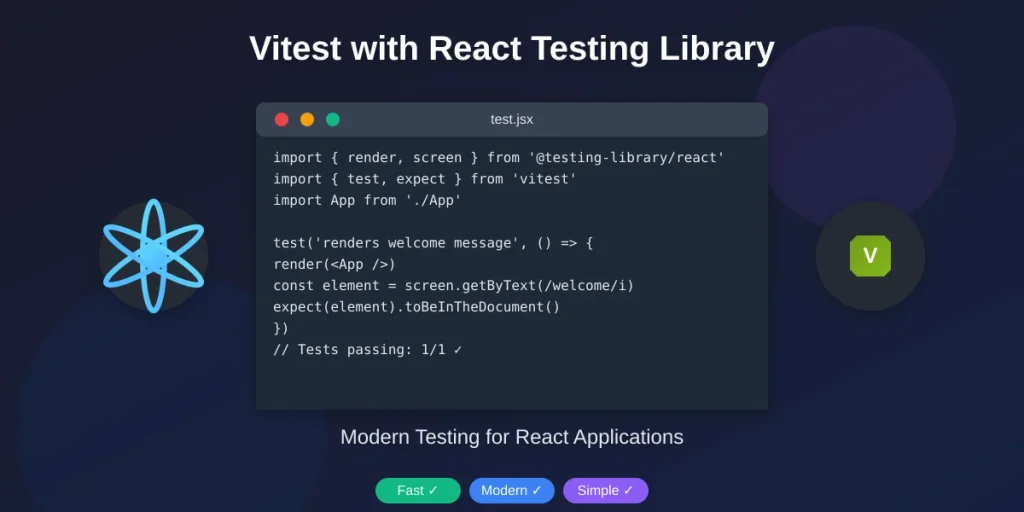
A comprehensive guide to setting up and using Vitest with React Testing Library for modern React applications built with Vite